


phenofhy (pronounced, fee-no-fi) Python package for phenotype analysis in the Our Future Health (OFH) trusted
research environment (TRE). phenofhy is designed to make extraction, processing,
and reporting of OFH phenotype data quick and repeatable inside DNAnexus. It is user-friendly, efficient and easy to install. Built for the OFH DNAnexus trusted research environment.
- Purpose-built for the OFH TRE and DNAnexus tooling.
- Easily extract and preprocess phenotype data in a few lines of intuitive code.
- Quick summaries and basic phenotype profile reporting to validate data early.
The phenofhy package is developed by Vincent Straub within the Leverhulme Centre for Demographic Science at the University of Oxford and is not affiliated with the Our Future Health research programme
- Researchers and students wanting to get started with analysing OFH phenotypes.
- Teams working inside the OFH TRE who need a repeatable preprocessing workflow.
- Analysts creating quick QA summaries and phenotype profile reports before GWAS.
phenofhy is designed to run inside the OFH TRE with DNAnexus tooling and
JupyterLab. It can be used on simulated data outside the TRE for local testing,
but the main workflows assume access to OFH datasets and the dx toolkit.
If testing out the package locally, install the released package with pip:
python -m pip install phenofhyFor development from a source checkout:
python -m pip install -e .Recommended runtime: Python 3.9+ (tested in OFH TRE JupyterLab).
To use the package inside a configured DNAnexus TRE JupyterLab session, initialize Phenofhy once for the project:
import phenofhy

phenofhy.init()
Initialization discovers the current project and dataset, extracts the OFH metadata dictionaries, uploads those files to the project, and creates a project configuration. The configuration is uploaded to the remote phenofhy/ folder. Later sessions can simply import and use Phenofhy; the configuration is downloaded automatically when it is not present locally.
Initialization requires:
- Python 3.9 or newer;
- the DNAnexus
dxtoolkit installed and authenticated; DX_PROJECT_CONTEXT_IDset by the TRE environment;- permission to read the selected dataset and upload files to the project.
Explore the full phenofhy documentation here: https://studiovincentstraub.github.io/phenofhy/
Where to start on the documentation website?
- New to
phenofhyor OFH phenotype analysis? Begin with "Getting Started" and then the "Quickstart" for a smooth introduction, followed by "Key Concepts". - Got your own data? After "Getting Started" and "Key Concepts", you are ready to dive in and start analyzing but can use the "Tutorials" to help.
- Looking for more? Check out "API reference" to deepen your understanding and the "Community & Support" section to request features and join the discussion"
from phenofhy import extract, process, calculate, profile, utils

# 1) Extract a small set of fields
extract.fields(
    output_file="outputs/raw/phenos.csv",
    fields=[
        "participant.registration_year",
        "participant.registration_month",
        "participant.birth_year",
        "participant.birth_month",
        "participant.demog_sex_2_1",
        "questionnaire.smoke_status_2_1",
    ],
)

# 2) Process participant data (derives age, sex, age_group)
df = process.participant_fields("outputs/raw/phenos.csv")

# 3) Summaries
summary = calculate.summary(
    df,
    traits=["derived.age_at_registration", "derived.sex"],
    stratify="derived.sex",
)

# 4) Profile report
report = profile.phenotype_profile(
    df,
    phenotype="derived.age_at_registration",
    output="outputs/reports/age_profile.pdf",
)

# 5) Upload your results
report = utils.upload_files(
   files="outputs/reports/age_profile.pdf",
   dx_target="results"
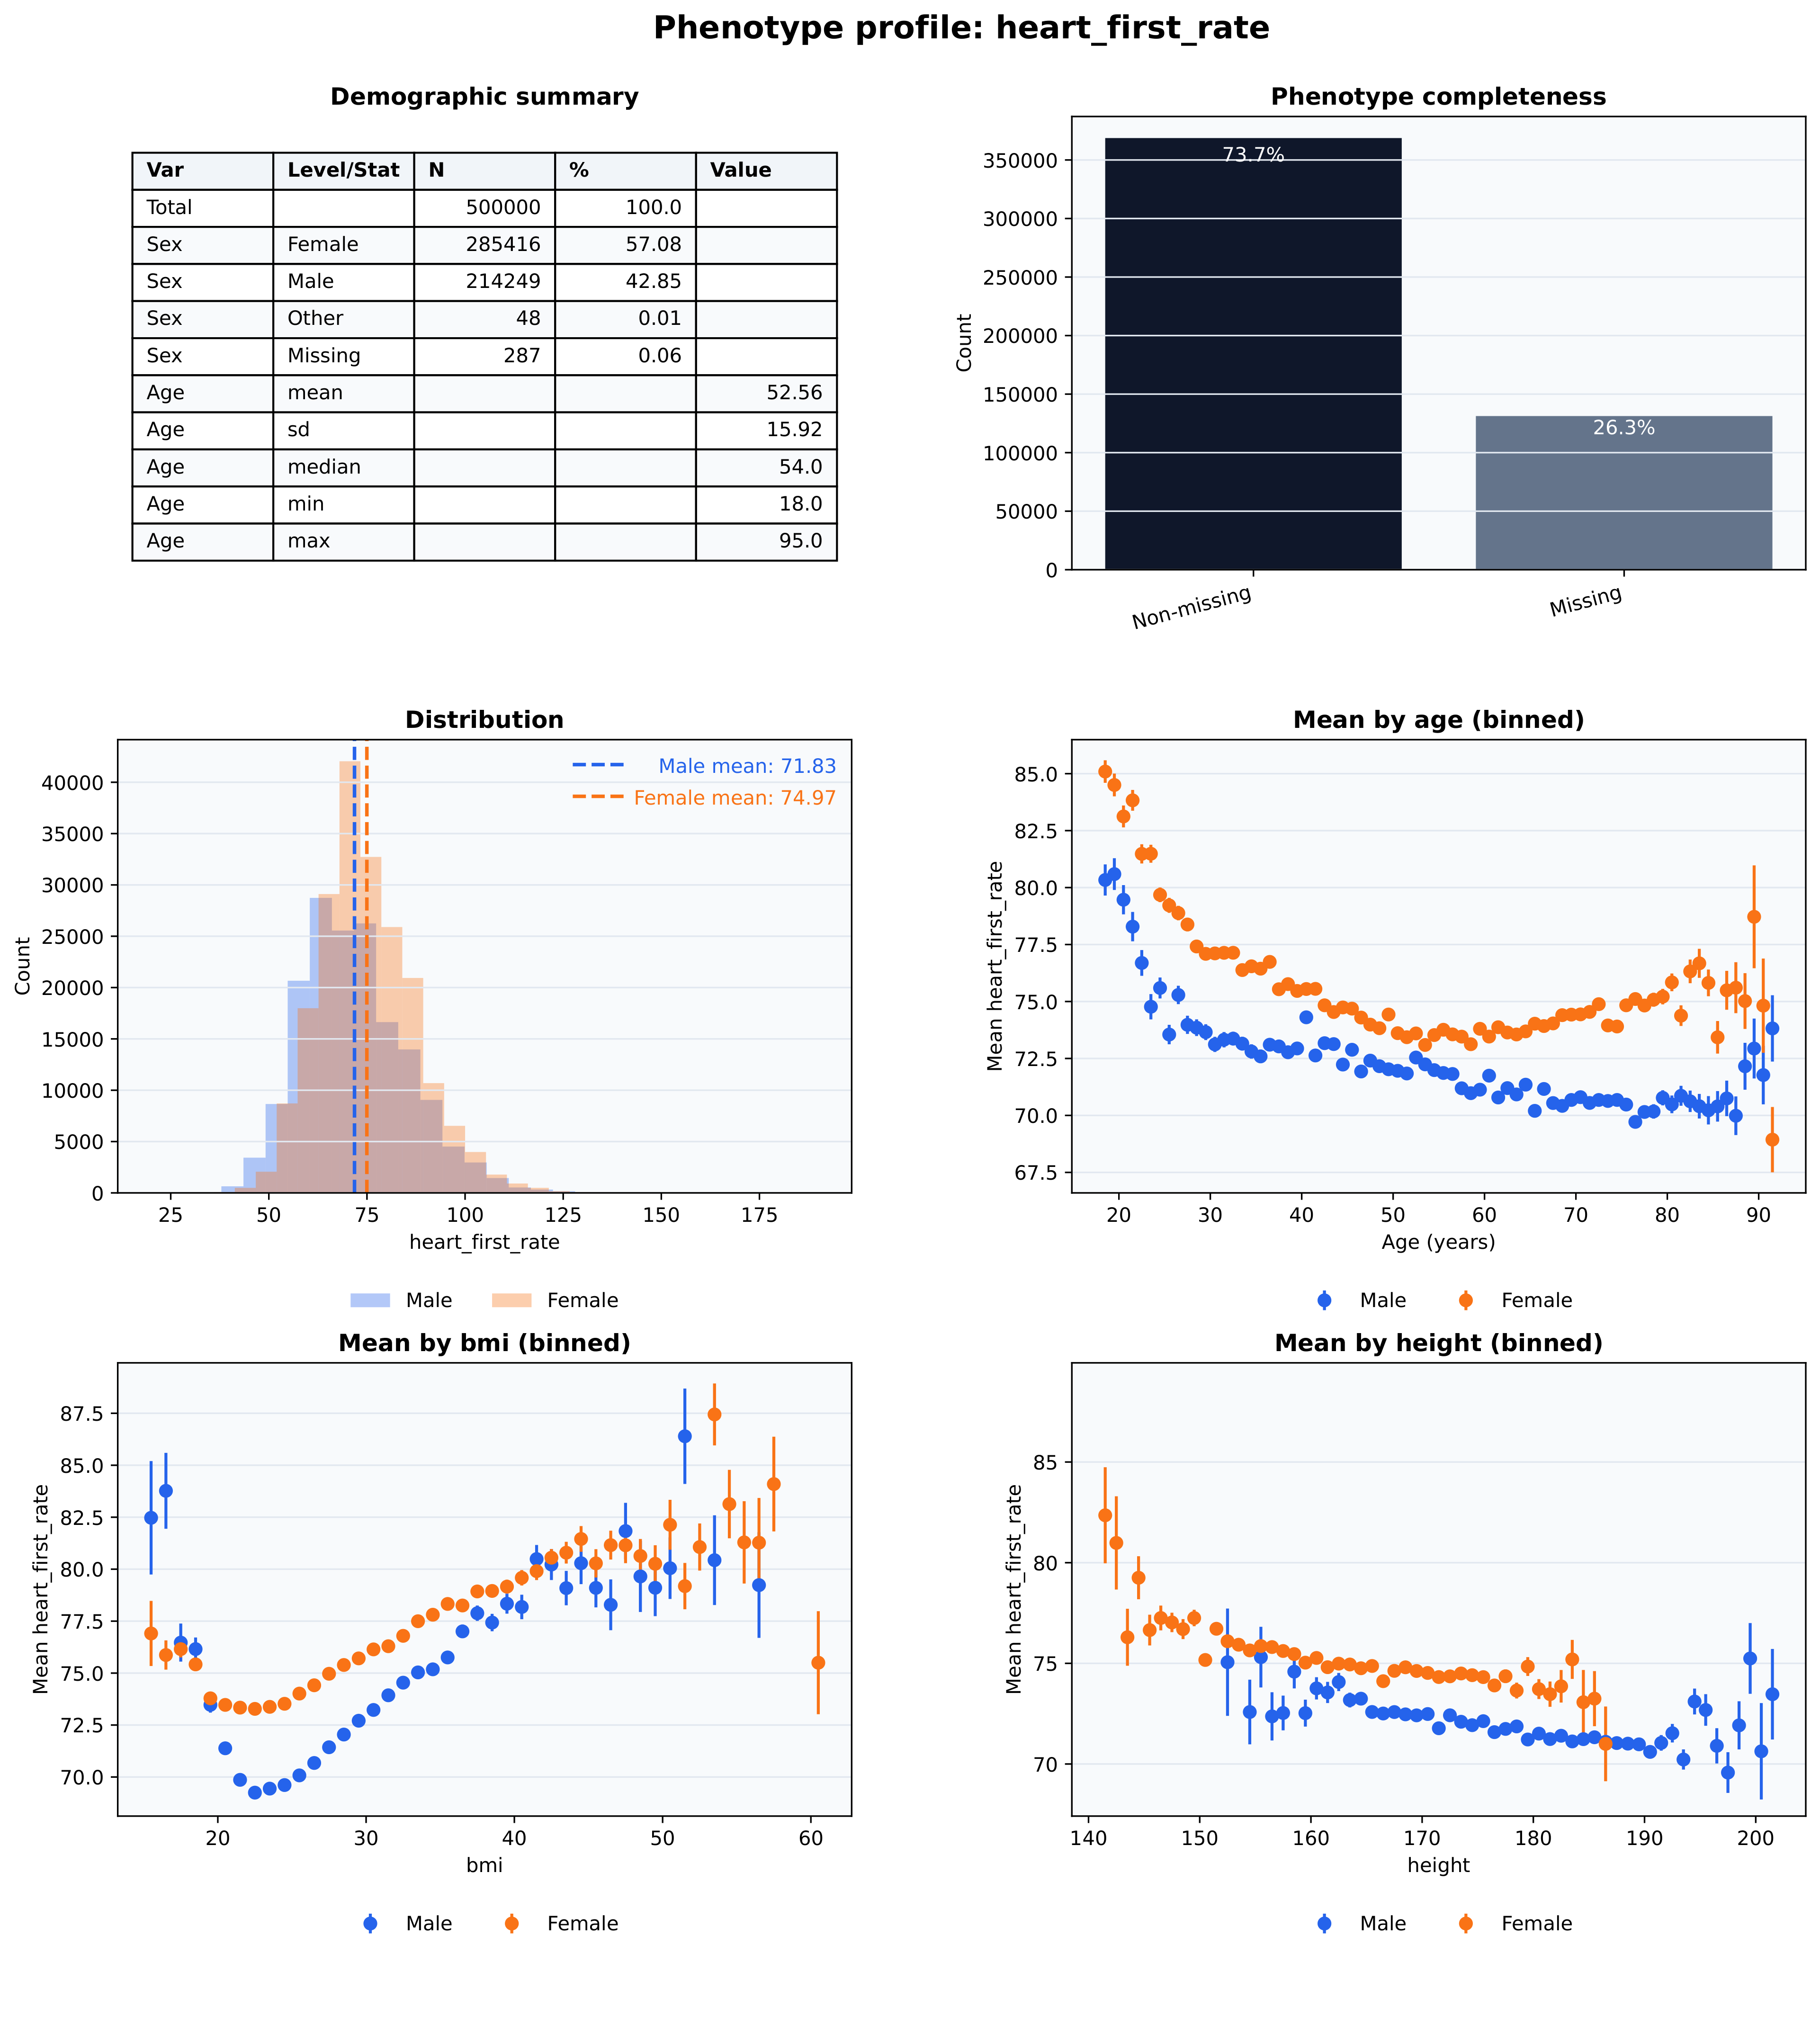
)Below is a phenotype profile report (using simulated data).
If you find a bug or want to suggest an improvement, open an issue or start a discussion in the repository.